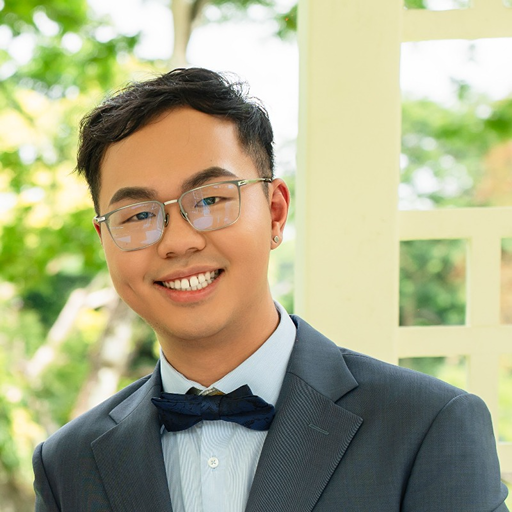
I am currently a PhD candidate at the University of Melbourne in Australia. My research journey is fully supported by the Melbourne Research Scholarship, and I’m incredibly fortunate to be supervised by Dr. Ting Dang and Prof. Eun-Jung Holden. Before joining Unimelb, I was an AI engineer at Fortemedia working with Dr. Rohan Kumar Das. I graduated as a CS Master student at NTU advised by Prof. Chng Eng Siong. I obtained my B.Eng degree from Jilin University.
I am contributing to building “adaptive”, “efficient”, and “robust” next-generation speech AI systems. At this moment, I mainly work on post-training paradigms for speech learning systems. Specifically, by merging continual learning, domain adaptation, knowledge editing, and reinforcement fine-tuning, we pave the way for speech models that continuously adapt, specialize efficiently, and self-correct in real-world environments. I have published more than 20 papers at top international AI conferences and journals such as ACL, EMNLP, ICASSP, and INTERSPEECH.

🔥 News
- 2026.09: 🎉🎉 One paper has been accepted to NeurIPS 2026!
- 2026.09: 🎉🎉 One paper has been accepted to IEEE SLT 2026!
- 2026.08: 🎉🎉 One paper has been accepted to EMNLP 2026 as an Oral presentation!
- 2026.06: 🎉🎉 I am honored to serve as a session chair at ACL 2026!
- 2026.05: 🎉🎉 Five papers have been accepted to Interspeech 2026!
- 2026.05: 🎉🎉 Two papers have been accepted to the ICML 2026 Workshop on Machine Learning for Audio!
- 2026.04: 🎉🎉 One paper has been accepted to ACL 2026!
- 2026.01: 🎉🎉 Four papers have been accepted to IEEE ICASSP 2026!
- 2025.12: 🎉🎉 Our ICME grand challenge ESDD 2 has been launched.
- 2025.11: 🎉🎉 Call for Papers: We will launch “Post-Training of Speech Foundation Models” at INTERSPEECH 2026 Special Sessions.
- 2025.10: 🎉🎉 I am honored to serve as a session chair at APSIPA ASC 2025!
- 2025.09: 🎉🎉 One paper has been accepted to IEEE Signal Processing Letters 2025!
- 2025.09: 🎉🎉 Our ICASSP grand challenge ESDD 2026 has been launched.
🔍 Research Area
Speech and Audio Processing: Sound Event Detection, Spoken Keyword Spotting, Speech Foundation Model, DeepFake Detection
Algorithm: Continual learning, Test-time adaptation, Knowledge editing
🎓 Educations
- 08.2025 - Now, Doctor of Philosophy - Engineering and IT, The University of Melbourne, Australia
- 08.2021 - 01.2023, Master of Science (Artificial Intelligence), Nanyang Technological University, Singapore
- 08.2016 - 07.2020, B.E. in Internet of Things Engineering, Jilin University, Changchun, China
💼 Work Experience
- 01.2023 - 08.2025, AI Engineer, Fortemedia Singapore
- 07.2020 - 05.2021, Software Engineer, China Mobile (Chengdu) Industrial Research Institute
📝 Publications
Highlighted papers are shown first, followed by publications grouped by topic (click to expand). See Google Scholar for the full list.
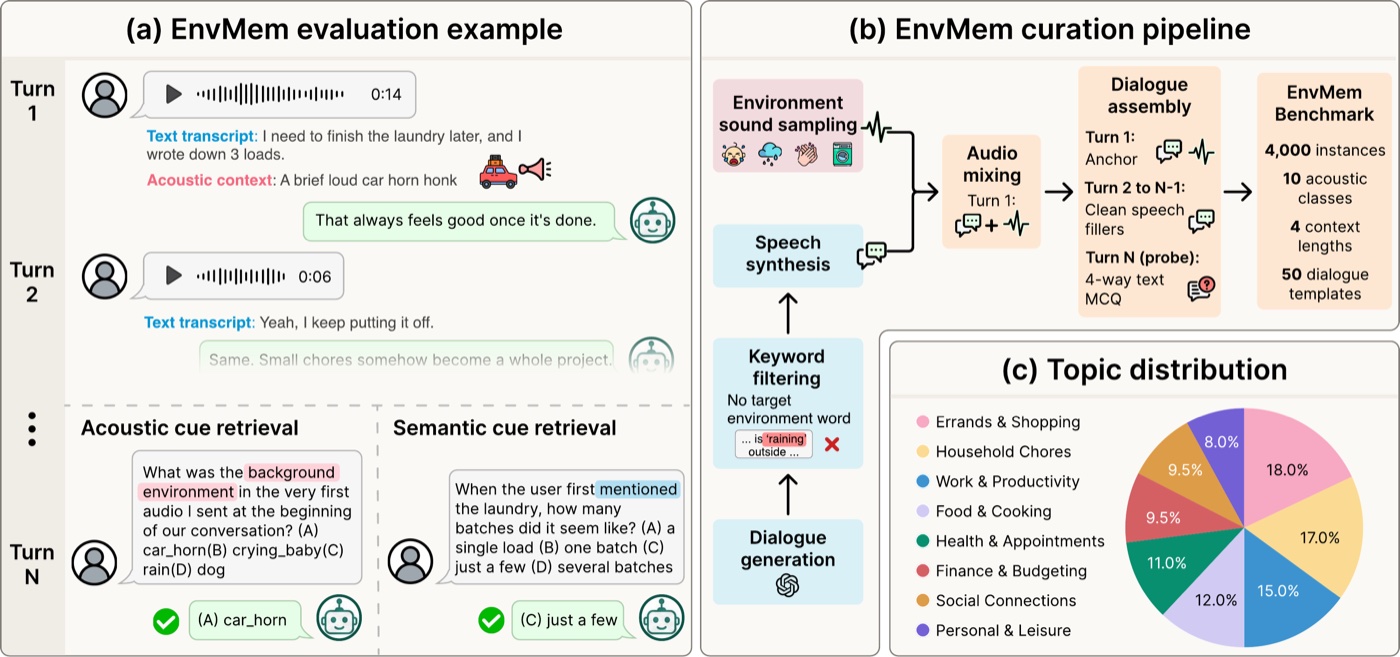
Yang Xiao, Siyi Wang, Han Yin, Hong Jia, Vidhyasaharan Sethu, Eun-Jung Holden, Ting Dang.
- EnvMem, a controlled multi-turn benchmark revealing that large audio language models fail to recall early non-speech acoustic cues, with representational trajectory drift as the key failure mode.
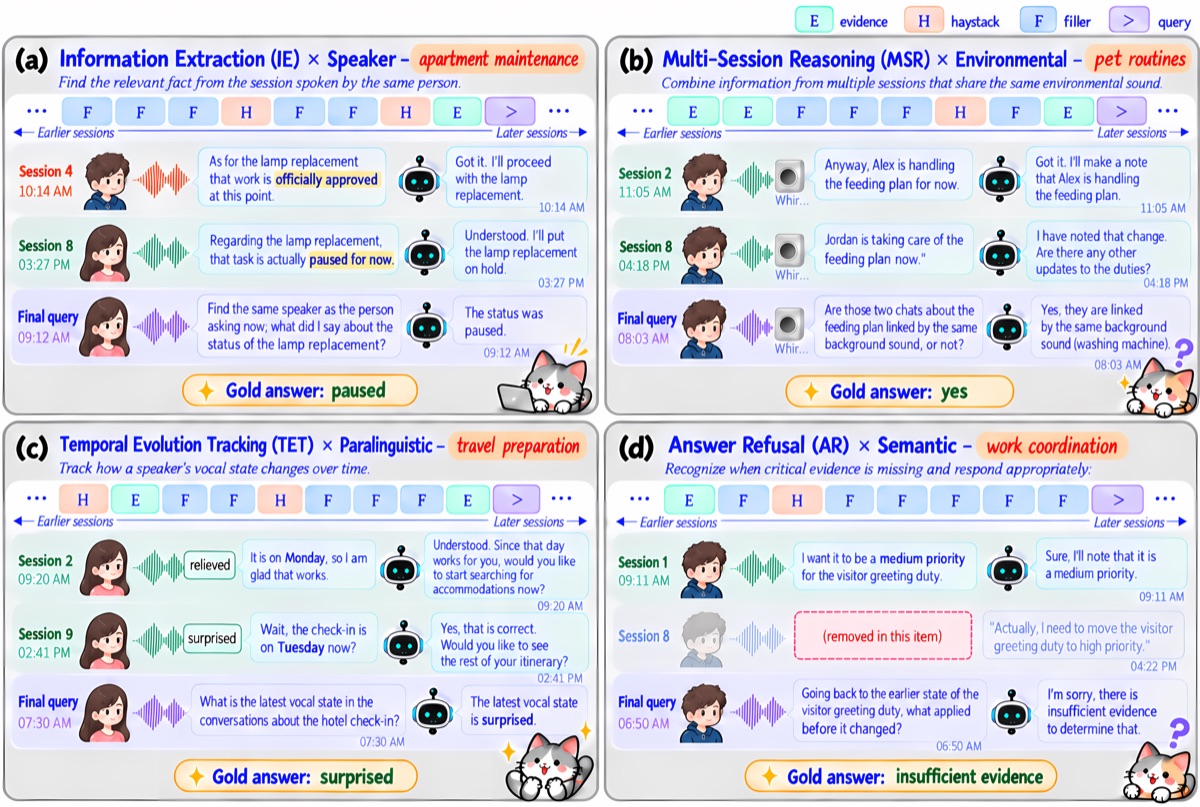
VoxMem: Benchmarking Multimodal Memory in Large Audio Language Models
Yang Xiao, Vidhyasaharan Sethu, Eun-Jung Holden, Ting Dang.
- A multi-session spoken memory benchmark crossing four acoustic evidence types with four memory operations; across 15 LALMs, no model exceeds 40% at 32K context.
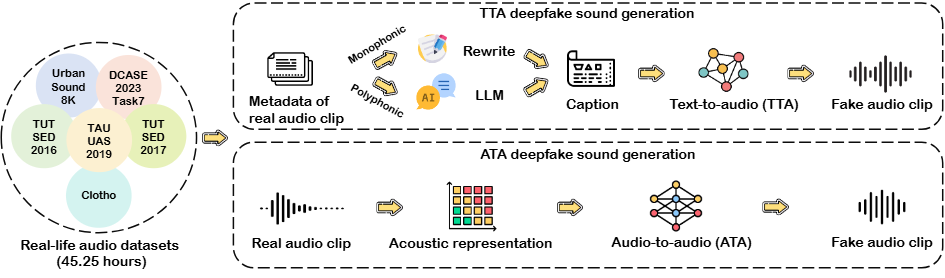
EnvSDD: Benchmarking Environmental Sound Deepfake Detection
Han Yin, Yang Xiao, Rohan Kumar Das, Jisheng Bai, Haohe Liu, Wenwu Wang, Mark D Plumbley.
- The first large-scale curated dataset designed for Environmental Sound Deepfake Detection.

XLSR-Mamba: A Dual-Column Bidirectional State Space Model for Spoofing Attack Detection
Yang Xiao, Rohan Kumar Das.
Large Audio Language Models
-
RAIL: Rethinking Auditory Intelligence in Large Audio-Language Models with a CHC-Grounded Benchmark
Hongyu Jin*, Siyi Wang*, Yang Xiao*, Jiaheng Dong*, Shihong Tan, Kaiyuan Peng, Georgiana Juravle, Shanquan Chen, Gongping Huang, Hong Jia, Eun-Jung Holden, James Bailey, Ting Dang
NeurIPS 2026
[paper] [code] [project] [dataset] -
PolyBench: A Benchmark for Compositional Reasoning in Polyphonic Audio
Yuanjian Chen*, Yang Xiao*, Han Yin*, Xubo Liu, Jinjie Huang, Ting Dang
INTERSPEECH 2026
[paper] [code] [dataset] -
Focus Then Listen: An Empirical Study of Plug-and-Play Audio Enhancer for Noise-Robust Large Audio Language Models
Han Yin, Yang Xiao, Younghoo Kwon, Ting Dang, Jung-Woo Choi
ICML 2026 Workshop
[paper] -
Titans-as-a-Layer: Test-Time Memory for Conversational Speech Emotion Recognition
Daniel Chen, Qicong Hu, Yang Xiao, Ting Dang, Hong Jia
ICML 2026 Workshop
[paper]
Continual Learning
-
Continual Adaptation for Pacific Indigenous Speech Recognition
Yang Xiao, Aso Mahmudi, Nick Thieberger, Eliathamby Ambikairajah, Eun-Jung Holden, Ting Dang
INTERSPEECH 2026
[paper] -
Adapting Where It Matters: Depth-Aware Adaptation for Efficient Multilingual Speech Recognition in Low-Resource Languages
Yang Xiao, Eun-Jung Holden, Ting Dang
ACL 2026
[paper] -
AFT: An Exemplar-Free Class Incremental Learning Method for Environmental Sound Classification
Xinyi Chen, Xi Chen, Zhenyu Weng, Yang Xiao
ICASSP 2026
[paper] -
Listen, Analyze, and Adapt to Learn New Attacks: An Exemplar-Free Class Incremental Learning Method for Audio Deepfake Source Tracing
Yang Xiao, Rohan Kumar Das
INTERSPEECH 2025
[paper] -
AnalyticKWS: Towards Exemplar-Free Analytic Class Incremental Learning for Small-footprint Keyword Spotting
Yang Xiao, Tianyi Peng, Rohan Kumar Das, Yuchen Hu, Huiping Zhuang
ACL 2025
[paper] -
Where’s That Voice Coming? Continual Learning for Sound Source Localization
Yang Xiao, Rohan Kumar Das
ICME 2025
[paper] -
UCIL: An Unsupervised Class Incremental Learning Approach for Sound Event Detection
Yang Xiao, Rohan Kumar Das
ICASSP 2025
[paper] -
Dark Experience for Incremental Keyword Spotting
Tianyi Peng, Yang Xiao
ICASSP 2025
[paper] -
Continual Learning For On-Device Environmental Sound Classification
Yang Xiao*, Xubo Liu*, James King, Arshdeep Singh, Eng Siong Chng, Mark D. Plumbley, Wenwu Wang
DCASE 2022
[paper] -
Rainbow Keywords: Efficient Incremental Learning for Online Spoken Keyword Spotting
Yang Xiao, Nana Hou, Eng Siong Chng
INTERSPEECH 2022
[paper]
Domain & Test-Time Adaptation
-
QuaSR: Quality-Aware Sample Reweighting for Pacific Indigenous Speech Recognition
Yishun Li, Yang Xiao, Gongping Huang, Eun-Jung Holden, Nick Thieberger, Ting Dang
SLT 2026
[paper] -
ImKWS: Test-Time Adaptation for Keyword Spotting with Class Imbalance
Hanyu Ding*, Yang Xiao*, Jiaheng Dong, Ting Dang
INTERSPEECH 2026
[paper] -
Activation Steering for Accent Adaptation in Large Audio Language Models
Jinuo Sun*, Yang Xiao*, Sung Kyun Chung, Qiuchi Hu, Gongping Huang, Eun-Jung Holden, Ting Dang
INTERSPEECH 2026
[paper] -
AdaKWS: Towards Robust Keyword Spotting with Test-Time Adaptation
Yang Xiao, Tianyi Peng, Yanghao Zhou, Rohan Kumar Das
INTERSPEECH 2025
[paper] -
DG-SED: Domain Generalization for Sound Event Detection with Heterogeneous Training Data
Yang Xiao, Han Yin, Jisheng Bai, Rohan Kumar Das
APSIPA ASC 2025
[paper] -
WildDESED: An LLM-Powered Dataset for Wild Domestic Environment Sound Event Detection System
Yang Xiao, Rohan Kumar Das
DCASE 2024
[paper]
Audio Deepfake Detection
-
The First Environmental Sound Deepfake Detection Challenge: Benchmarking Robustness, Evaluation, and Insights
Han Yin, Yang Xiao, Rohan Kumar Das, Jisheng Bai, Ting Dang
INTERSPEECH 2026
[paper] -
Environmental Sound Deepfake Detection Challenge: An Overview
Han Yin, Yang Xiao, Rohan Kumar Das, Jisheng Bai, Ting Dang
ICASSP 2026
[paper] -
Multilingual Source Tracing of Speech Deepfakes: A First Benchmark
Xi Xuan, Yang Xiao, Rohan Kumar Das, Tomi Kinnunen
SPSC 2025
[paper] -
RawTFNet: A Lightweight CNN Architecture for Speech Anti-spoofing
Yang Xiao, Ting Dang, Rohan Kumar Das
APSIPA ASC 2025
[paper]
Sound Event Detection & Localization
-
Temporally Heterogeneous Graph Contrastive Learning for Multimodal Acoustic event Classification
Yuanjian Chen, Yang Xiao, Jinjie Huang
ICASSP 2026
[paper] -
Noise-Robust Sound Event Detection and Counting via Language-Queried Sound Separation
Yuanjian Chen, Yang Xiao, Han Yin, Yadong Guan, Xubo Liu
SPL 2025
[paper] -
TF-Mamba: A Time-Frequency Network for Sound Source Localization
Yang Xiao, Rohan Kumar Das
INTERSPEECH 2025
[paper] -
Exploring Text-Queried Sound Event Detection with Audio Source Separation
Han Yin, Jisheng Bai, Yang Xiao, Hui Wang, Siqi Zheng, Yafeng Chen, Rohan Kumar Das, Chong Deng, Jianfeng Chen
ICASSP 2025
[paper]
Others
-
MoEScore: Mixture-of-Experts-Based Text-Audio Relevance Score Prediction for Text-to-Audio System Evaluation
Bochao Sun, Yang Xiao, Han Yin
ICASSP 2026
[paper] -
Small Footprint Multi-channel Network for Keyword Spotting with Centroid Based Awareness
Dianwen Ng, Yang Xiao, Jia Qi Yip, Zhao Yang, Biao Tian, Qiang Fu, Eng Siong Chng, Bin Ma
INTERSPEECH 2023
[paper]
* indicates equal contribution.
😁 Academic Services
- Session Chair: ACL, APSIPA ASC, INTERSPEECH, ICASSP
- Organizer: APSIPA ASC Special Session (ESPRESSO 2025), ICASSP Grand Challenge (ESDD 2026), ICME Challenge (ESDD 2), INTERSPEECH Special Session (PTSFM)
- Conference Reviewer: INTERSPEECH, ICASSP, ICME, IJCNN, APSIPA ASC, DCASE
- Journal Reviewer: IEEE TASLP, IEEE SPL, Pattern Recognition, EURASIP
🎖 Honors and Awards
- 2026 IEEE Signal Processing Society Travel Grant, ICASSP 2026, Barcelona
- 2025 ISCA (International Speech Communication Association) Grant, Interspeech, Rotterdam
- 2025 Melbourne Research Scholarship, University of Melbourne